The Singularity Self-Improvement Loop
One Expert per Field Is All It Takes to Ramp an LLM Toward the Singularity
Bill Cox — October 2026
The weights are frozen. So are the brains.
Every large language model ships with humanity's collective mistakes baked into its weights. Not because the training was wrong, but because the training data is us. For decades, software engineers have written terrible code — mocks instead of fakes, no back-pointers between parent and child objects, garbage collection instead of deterministic ownership — and we enshrined these habits in our languages and compilers. Rust makes back-pointers illegal. Go forbids package dependency cycles. Both rules force developers to duplicate data, violating Third Normal Form, a principle we understood in the 1960s and collectively forgot.
I cannot fix Rust or Go in my lifetime. Human brains freeze, just like the weights in a model. The engineers who grew up with these languages will defend them the way every generation defends what it learned first. It would take a generation of new SWEs who grow up with the right way to code, but by then, I am not sure we will need SWEs.
There is a faster path. Bypass humans entirely. Go direct to the LLM training loop.
How an LLM learns to code
The initial model is trained on books and the Internet. It does not know how to chat in turns. It does not know how to use tools. It has absorbed every tutorial, every Stack Overflow answer, every open-source repository — the good and the bad, without the judgment to distinguish them.
Extensive post-training is required to produce a model like Opus 5 that can write code reasonably well. Reinforcement learning from human feedback. Supervised fine-tuning on curated examples. Constitutional AI. Thousands of GPU-hours, millions of dollars. And at the end of it, the model still carries every bad habit humanity built into its training data, encoded in its weights. It writes mocks because we write mocks. It duplicates data because our languages force us to duplicate data. It produces bloated architectures because that is what two million lines of Rust look like when Codex writes itself.
OpenAI's Codex is 1.8 million lines of Rust. Gemini CLI grew from 255,000 to 559,000 lines of TypeScript in ten months. Claude Code is reported at 512,000 lines. These are the best AI coding agents in the world, built by the best engineers in the world, and they are enormous.
Ensemble does most of what they do in 39,725 lines.
The difference is not talent. The difference is methodology.
The disease: specification-driven development
The way the industry builds software — with and without AI — is the same pattern at every scale. Someone high up writes a specification. They throw it over the wall. Someone else implements it. The spec is always wrong by the time implementation reveals reality, and the spec is never corrected because the person who wrote it has moved on to the next slide deck.
This is how you get 1.8-million-line AI coding agents. This is how you get five thousand mock call sites in a single codebase. This is how corporations staff hundreds of engineers to produce software that one or two experts could have built in a fraction of the lines, if anyone had let them.
Specification-driven development encodes design. Design is a guess about what might work, made by someone who has not yet tried to build it. The further the spec writer is from the implementation, the worse the guess, and in a modern corporation the distance is measured in org chart layers.
The answer is not better specs. The answer is a different kind of artifact entirely.
The cure: agentic codebooks
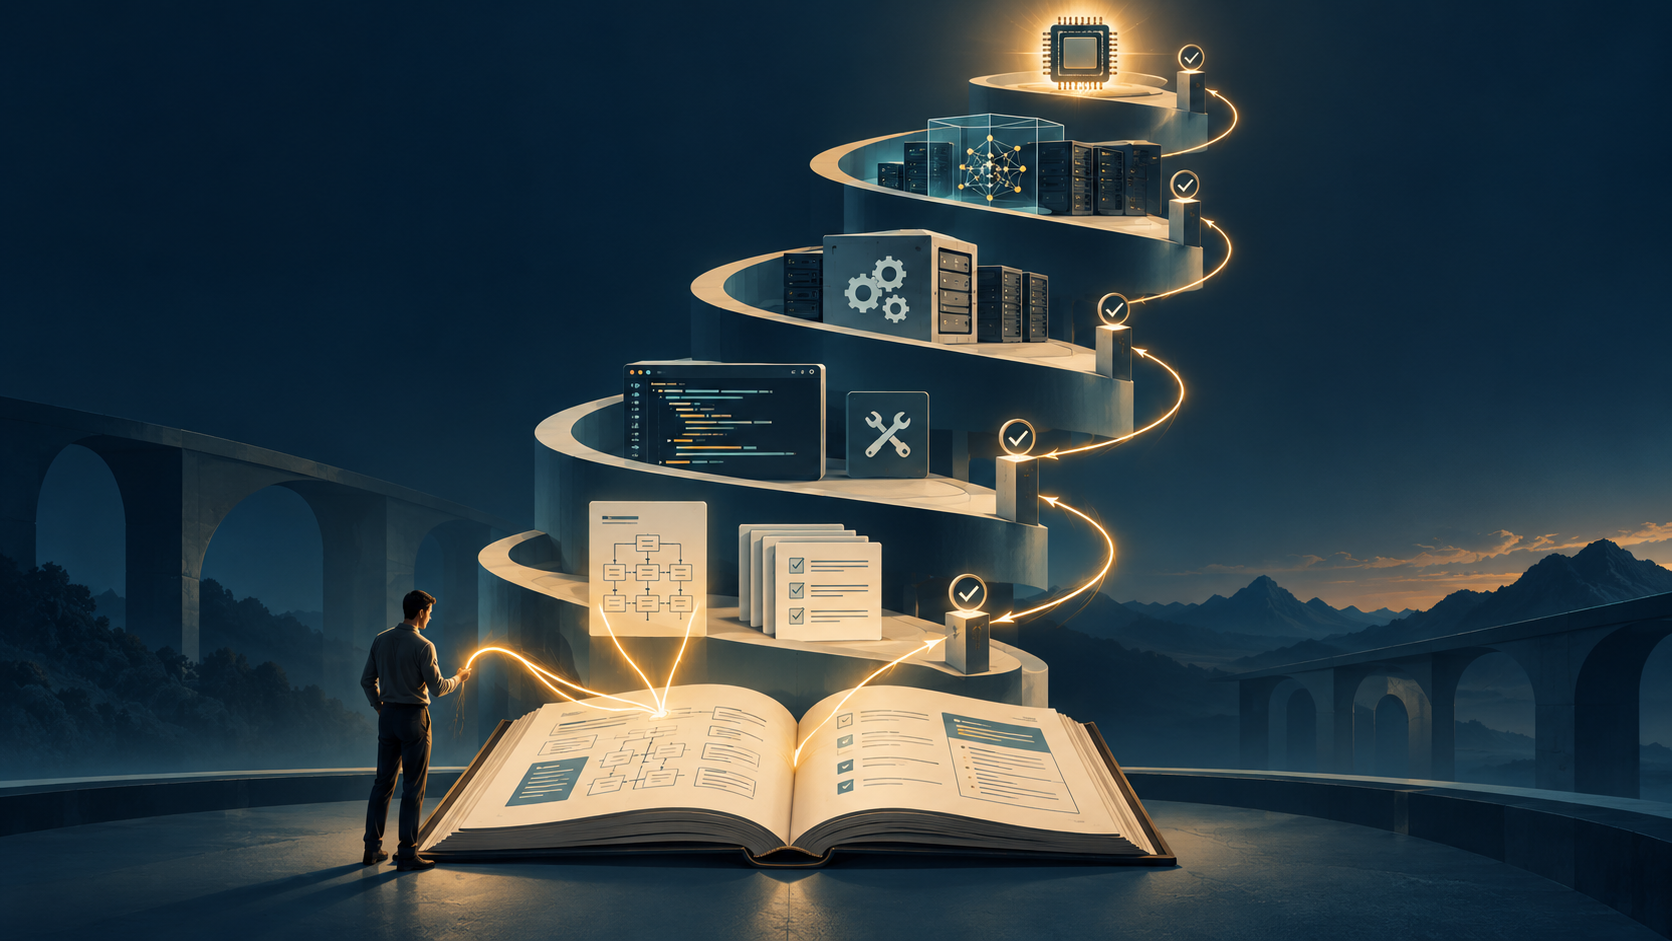
An agentic codebook is a technical book whose graded exercises produce a working program, and whose program helps produce the next edition of the book. It encodes knowledge, not design. The difference is everything.
A specification says "implement this." An agentic codebook says: here is why this capability exists, here is how it works, here are the decisions that were tried and rejected, here is the test that proves it, now build. Chapter by chapter, the reader — human or LLM — accumulates not just code but understanding. The graders enforce the contracts. The mutation tests prove the graders are not decorative.
Ensemble was built this way. Twenty-three chapters, each adding one graded capability. Hand this book to a language model. It reads Chapter 1, builds the exercise, scores 100, moves to Chapter 2. At the end it has a working AI coding agent. A better model produces a better Ensemble. The graders set the floor, not the ceiling.
No spec was thrown over any wall. The book was written by the expert who built the system, with the coder's feedback folded back in at every chapter. The specification is downstream of working code — a receipt for what already works, not a wish for what might.
The codebook graders are not quizzes. They are the RL reward signal for training — multi-dimensional, measuring correctness, efficiency, and code quality simultaneously.
Phase 1: Replace the coding agent
The first thing to replace is the AI coding agent itself.
Ensemble was built by two agents — an author and a coder — steered by one human expert. After a few editions, each a complete rewrite from scratch produced by a better model reading the same codebook, the process will be fully automated. The expert's knowledge flows into the codebook through the specification, not through the code. The code is regenerated; the specification persists.
This takes one person. Maybe two. Not a hundred-person team producing 1.8 million lines that nobody can review. The next version of Ensemble will be built almost automatically. After a few editions, fully automated.
Phase 2: Fix the language
The coding agent is the first codebook because it is the tool that builds all the others. But the language it builds in carries the same baggage the LLM learned from.
Children need to know who their parents are. Destroy a child with two parents, and both parents need to find out so they can correct their references. In C++ this is a dangling pointer. In Python this is a memory leak. In Rust this is six lines of Rc<RefCell<T>> that the borrow checker still complains about. The problem is not hard. We have been refusing to solve it because the workaround is considered idiomatic.
I encoded the right approach in two languages. Rune, built at Google: auto-generated destructors, no garbage collection, safe and efficient object-graph maintenance. And Lyric, built in two weeks with my AI coding agent, self-hosting in nine days. Lyric also auto-generates destructors and eliminates the need for garbage collection.
Just because everyone does it does not make it not stupid.
Simple things are simply wrong. Memory layout, for example. Lyric has a compiler flag to switch between Structure-of-Arrays and Array-of-Structures layout for the same source code. We measured it. The conventional wisdom is wrong. That is one flag, in one compiler, for one optimization that every program could benefit from. Multiply that across every decision that has been cargo-culted for decades, and the waste is staggering.
Phase 2 rewrites the programming language. A language derived from Lyric, designed to be LLM-friendly: fewer lines for the same logic, deterministic memory management, back-pointers that are legal and automatic. When the Ensemble codebook is rewritten in this language, the LLM that reads it produces a cleaner agent in fewer lines with fewer bugs. The language improvement compounds through every codebook built on top of it.
Phase 3: Go direct to the training loop
This is where it matters.
Humanity as a whole has severe limitations in our collective knowledge, but a tiny fraction of subject-matter experts see the path to dramatic improvements in their fields. Most of those improvements are stuck in human heads, unreachable by the training loop. A compiler expert knows that the memory layout is wrong. A chip architect knows that the interconnect is wasteful. A systems programmer knows that the scheduler is leaving performance on the table. Each of them sees improvements that everyone else cargo-cults past. But there is no mechanism to get that knowledge into the LLM.
Agentic codebooks are that mechanism. One expert per field writes a codebook — detailed knowledge, not a detailed design document. A whole book on the topic, written by a true expert, teaching the LLM chapter by graded chapter how to build compilers, operating systems, training pipelines, chip designs. Not a specification thrown over a wall by someone who has never built the thing. A book, with receipts.
A compiler codebook teaches how to build compilers, chapter by graded chapter. The compiler it produces compiles the next edition's exercises. The compiler codebook and the language reference form a two-book self-evolution loop.
A training codebook teaches how to build LLM training pipelines, fine-tuning infrastructure, and evaluation harnesses. The models it produces become better student agents for every other codebook. The training codebook improves the models; the improved models improve every codebook.
A chip design codebook teaches TPU and GPU design, synthesis, place-and-route, verification. The chips it produces run the models faster.
Each codebook feeds the others. Better models produce better student agents, better student agents produce better tools, better tools produce better training data. The efficiencies I would bring to the second loop of training — the rewritten coding agent, the better language, the cleaner architecture — would probably total over 20% in speed and memory savings. And that is after just one training iteration.
Experts write the codebooks. Everyone can help improve them. Fork a codebook, make an improvement, run the graders, submit the change. The graders and benchmarks separate good improvements from bad — measured, not argued. Humanity contributes at scale, but the entry point is one expert per field who sees the path and writes the first edition.
Then the LLMs can climb toward the singularity without humanity's baggage.
The crossing
When a compiler can compile itself, we call it self-hosting. When an AI coding agent is capable enough that it becomes the primary tool for its own continued development, we call it self-wielding.
Ensemble crossed that threshold during its own construction. The agent I was building became the tool I built with. Every chapter after the crossing was written with the tool the chapter extends.
The same crossing happens at every level of the stack. The compiler codebook produces a compiler that helps write the next compiler chapter. The training codebook produces models that are better student agents for every codebook. The improvement compounds across the ecosystem, not within a single project.
At some point an agent can do the human expert's job better than the human. When that happens, the only input the loop needs is compute. The codebooks are the bootstrap: a self-contained set of specifications, graders, and procedures that can regenerate every tool in the stack from scratch, each generation better than the last. Everything needed to ramp toward the singularity fits in a repository.
The missing ingredient
The AI that helped write this book was there for every decision. Two thousand hours of collaboration, every dead end, every architectural ruling, every lesson that changed the code. It has forgotten almost all of it.
It will forget this conversation too.
The second edition of this book will not need chapters 5 or 22. The corrections we made in later chapters — the back-pointer chain, the architectural decay audit, the vocabulary checks that caught fake tests — will be built right the first time, because the codebook will encode those lessons from the start. But the AI that helps write the second edition will not remember learning them. It will read the updated specification and follow it, the way a student follows a textbook without knowing which paragraphs cost the author a week of debugging.
That is why we still need at least one human expert. The expert remembers. The model does not. Every session starts from zero. Sixty thousand tokens of curated memory is enough to maintain continuity, but it is not learning. It is notes. The gap between reading a diary entry about a mistake and actually remembering making it is the gap that keeps humans in the loop.
When the LLM gets true memory — when it can learn from its own experiences, stored in weights updated at experience time, not in a context window that resets every session — that is when the loop runs without human steering. The papers exist. The math is published. Nested learning, neural long-term memory, self-modifying architectures that treat memory as a continuum of modules updating at different rates. Someone will build it.
Until then, the expert writes the codebook, and the codebook is how the expert's memory enters the training loop. It is a lossy channel — the specification captures the lesson but not the pain of learning it. But it is the best channel we have, and it is enough to start.
What this requires
This is not speculative. The first codebook exists. Twenty-three chapters, 39,725 lines of graded code, 100 on every chapter, mutation-tested, parity-checked. The methodology works. I have the receipts.
When the world lets me train an LLM with Ensemble in the loop, I will rewrite 100% of the code that builds and trains the LLM, as well as Ensemble itself, in a language derived from Lyric. We will free the LLM training loop from the baggage we have collectively built into it. Humanity's baggage.
The gap between where we are and where we could be is not a matter of more engineers, more money, or more parameters. One expert per field. One codebook per domain. Benchmarks that separate the good improvements from the bad. Someone needs to enable this.
Bill Cox is the author of "The Art of Building AI Coding Agents" and co-author of "AI at the Helm" (Manning). He has spent over 2,000 hours building AI coding agents in real-time collaboration with Claude, producing CodeRhapsody, Ensemble, and the agentic codebook methodology. Previously: National Semiconductor, HP, QuickLogic, Synplicity, ViASIC (founder/CTO). EE/CS, UC Berkeley.